An Algorithmic Lucidity

a blog

October 2026

Accidentally Misleading People Should Be Embarrassing; Or, Higher Innocence

Embarrassment and Innocence

Sometimes we say things that we think are true—perhaps even things that are true—which end up causing reasonable people to conclude something false. It's tempting to relate to such a situation primarily in terms of maintaining the innocence of one's soul—to say, fine, my readers became more wrong, but I'm not to be judged for it because I believed what I was saying; I wasn't being misleading just because the people who believed me were thereby led into falsehood.

The temptation reflects a confusion as to the nature of the judgment. Mostly, people don't care about judging the innocence of your soul; they care about whether they'll be led into falsehood the next time they take the risk of believing what you say—if there is a next time. If you want there to be a next time and you're going to have social emotions about it, the most productive emotion is embarrassment rather than defensiveness.

The function of embarrassment as a social emotion is as a signal of appeasement and social repair: embarrassment says, "I'm aware that I've become visible in a socially undesirable way; please don't take it as representative of me."

The socially undesirable appearance can come apart from any intended or actual wrongdoing. Jewish law has a concept of marit ayin, "appearance to the eye": the law prohibits actions that would themselves be permissible if they didn't create the appearance of a prohibited act. Hanging up wet clothes to dry on the sabbath is prohibited, because it looks like you were doing laundry on the sabbath (even if the clothes actually got wet for some other reason). One function of the marit ayin doctrine is to deny plausible deniability to norm-violators (as someone might try to do laundry on the sabbath if they felt secure that no one would punish them for merely hanging up the wet clothes). Those who want to be known for keeping the sabbath need to pay a price that's more expensive for sabbath-violators to pay; if you care about maintaining the norm itself, it shouldn't be much extra trouble for you to furthermore care about maintaining the appearance of the norm.

One time, I accidentally joined a work call unmuted while my housemate was playing a loud video game. I was deeply embarrassed, because it looked like I was playing video games during work hours. I think my marit ayin-like embarrassment was serving a useful socio-psychological function, even though it was my housemate's game and I was in fact totally innocent in my soul. If I were the sort of person who was totally unashamed about creating the appearance of slacking off, then I think my manager and coworkers would have reason to doubt my commitment to productively working from home.

Similarly, people who are visibly embarrassed after having accidentally misled people can be counted on to work hard to make sure that people won't regret believing them next time. Defensive people won't, because, well, why would they? They didn't do anything wrong.

Two Case Studies About Accidentally Misleading People

Once, I suspected an ideological rival of misrepresenting a citation: they had linked to a webpage featuring an embedded PDF of an essay, but when I used my web browser's "Ctrl-F" search functionality with appropriate search terms to see what in the essay justified their claim, I came up empty. When considering whether to escalate to complaining more loudly about my rival over this (after the rival didn't respond to a blog comment and DM), I mentioned the matter to a third party—who pointed out that the essay did contain my search term! On further testing, it appeared that my web browser's Ctrl-F behavior depended on which page element had focus: if the user had last clicked inside the embedded PDF viewer, the search returned results inside the PDF, but not if the user had last clicked elsewhere on the page.

I was so embarrassed.

To be clear, I knew I was innocent in my soul: the browser UX bug wasn't my fault, and if the browser hadn't been buggy, then my initial search would have succeeded and I never would have complained. I certainly didn't lie. (I didn't say that I read the essay and verified that it didn't support the claim, which would have been false; I said the Ctrl-F search came up empty, which was true.)

But the innocence of my soul didn't matter. I knew that raising a suspicion that turned out to be false looked bad for me, even if there was ultimately a perfectly reasonable explanation for my actions. If I didn't want to look bad, I couldn't count on everyone hanging around to listen to my perfectly reasonable explanation for why it was all the Firefox developers' fault. I would need to make some sort of generalizable change to my policy—perhaps, reading the entire PDF myself next time before raising the suspicion that an ideological rival was misrepresenting it.

(Recounting this seven years later, I went back and downloaded the PDF. Excluding the title page and the endnotes, it was six pages.)

⁂

Another time, a journalist wrote an article paraphrasing a source as saying that it "could be unfair" for journalists to discuss "both critics and supporters" of some controversial public figure and that they should instead "somehow prove statistically which side was right." I was familiar with the source's work, and the paraphrase didn't sound like something she would say. I brought up that line from the article when I had occasion to talk to the same journalist three years later: he maintained it was fair, so I asked the source about it afterwards. She told me that she recalled telling the journalist that she "wasn't a huge fan of 'both sides' journalism, where you just find someone with one opinion and someone with the other opinion" rather than trying to figure out the truth; she had also given suggestions for data sources that might bear on claims about the public figure's influence.

I took that statement as confirmation of my suspicion that the paraphrase in the article was misleading. "[S]omehow prove statistically which side was right" leads readers who aren't familiar with the source's work to imagine that she has an unreasonable faith in the power of statistics to resolve all questions, whereas voicing skepticism of false balance is eminently reasonable. "Somehow" implies vagueness, but pointing out data sources that bear on some question is supplying a specific "how."

When I complained about this again to the journalist, he didn't seem embarrassed. "I had to boil down what she said to plain English," he said. I said that it hadn't worked. He said it did. He recounted that the source had objected when he said his coverage would represent both views of the public figure. When I interrupted to insist that it seemed like a bad paraphrase when compared to what the source had told me later, he said, "Is that necessarily what she said to me?"

And in absolute fairness, maybe it wasn't, necessarily. I of course was not present for the years-prior conversation between the journalist and the source; I don't have the recording, if there was one. Even if the source can be assumed to be an authority about what she meant to say, I cannot with absolute certainty rule out the scenario where the "somehow prove statistically which side was right" line was a reasonable paraphrase of the words she had literally said at the time and that her reconstruction years later of what she remembered saying was unintentionally injecting more nuance after the fact. The source apparently hadn't objected during a fact check call. If the journalist had reasonably paraphrased the words that were said to him at the time, then he was innocent in his soul. Even if his readers walked away with a distorted impression of what the source privately believed (but did not manage to successfully communicate in the interview), the miscommunication wasn't his fault.

I still think this episode looks bad for him and that he should have been embarrassed, because there should have been generalizable policy changes that could have prevented this class of error—perhaps, thinking more carefully about whether a paraphrase that makes a subject look unreasonable truly reflects the subject's views before going to print with it. Potential sources deciding whether they should talk to the journalist are mostly worried about the risk that their views will end up being miscommunicated, not whose fault a miscommunication would be if it happened. Unlucky accidents do not impinge upon the innocence of one's soul under the moral law, but the moral law is unmercifully permissive about everyone else's right to avoid unlucky people.

Higher Innocence

And that's why accidentally misleading people should be embarrassing: because the desire to avoid such embarrassment motivates a counterfactual reduction in such incidents of people being misled, notwithstanding that it was a totally unintentional accident and the speaker is perfectly innocent in their soul.

That's the conclusion of the post. Thanks for reading!

... or that's how I'd prefer to end the post, with a message of absolution and hope. Absolution—that those whose actions have propagated falsehood need not question what we know to be true of our souls. And hope—that we all might learn to do better in the future. There's just one little nuance that continues to haunt me, that I could not, unfortunately, end the post without explaining. (Not because I didn't try, but because my prereader Said Achmiz didn't let me get away with it.) Just a tiny subtlety, almost irrelevant, really, affecting almost none of the logic except to clarify that souls aren't real.

I've been writing this post to try to get through to people who are resistant to noticing when they've been misleading because they're terrified of judgment and social punishment. When you point out to them that their words led reasonable readers to walk away with the wrong model, they double-triple-quadruple down on playing dumb, insisting that they weren't lying, and that even if readers ended up being more wrong, it wouldn't be any substantial evidence against their integrity. This post has been trying to offer these people some moral absolution (which I don't care about one way or the other) in exchange for orienting towards the problem that I actually care about (of creating accurate shared maps): to say, look, I believe that you weren't lying, I believe that you're innocent in your soul, but the part where reasonable readers walk away with the wrong model is still a problem you should care about, even if it was an accident.

But was it an accident? Was it, really? It is written that the one who wishes to believe asks, "Does the evidence permit me to believe?" while the one who wishes to disbelieve asks, "Does the evidence force me to believe?" If you have a bottom line that you want to believe, and you go around looking for evidence that permits you to believe it, I really have to question in what sense it's an "accident" if you end up misleading people towards your bottom line.

It's surely an accident in some sense. The browser bug really wasn't my fault. But if I was too lazy to read six pages to check when it was my rival, but would have read the six pages if it had been my ally, that's a reason people should be suspicious when I claim that my rivals did something wrong. I wasn't lying, and that's a kind of innocence, but the cold light of "Six pages? Really?" makes me want to aspire to a higher form of innocence.
San Francisco State University in Twilight

You will agree that for a woman who has fought three duels, all of them kills, indulging in such fears is ludicrous. But what's around the corner now is a duel so big that I don't think I have the guts for it; in Faust's words: Verweile doch, du bist so schoen! Keep it as it is. Don't change. [...] Take my life but don't take away the meaning of my life.

—"When It Changed" by Joanna Russ

I've been crashing Prof. Lai's "Advanced Topics" class this semester, on Fourier analysis plus enough functional analysis to get by (since the University can't afford to offer functional analysis as a regular class anymore). It's not obviously a good use of my time, but now that I've started, I have to see it through. I could try to tell a story about impact: I am leveling up my math chops, which will be useful for understanding natural abstractions or singular learning theory or mechanistic explanation, which will be useful for—but maybe it's less embarrassing to not try to sell a story. Call it luxury consumption during garbage time. I've lived a good life, in some ways if not others. I could choose to drown in oceans of regret over all the songs I never finished and stories I never wrote and math I never learned when I was young, in the before-time when there was still enough clock in the timeline for these things to matter—or I could choose to do something with the time I have now, which doesn't.

On Wednesday 16 September, the class had its first examination. (When I had dropped by office hours on Monday, Prof. Lai had said I could take it, but that he might not grade it.) I hadn't prepped enough and did poorly, blanking on two parts. I didn't hand in the paper, but GPT-6 Astra later gave it 58%.

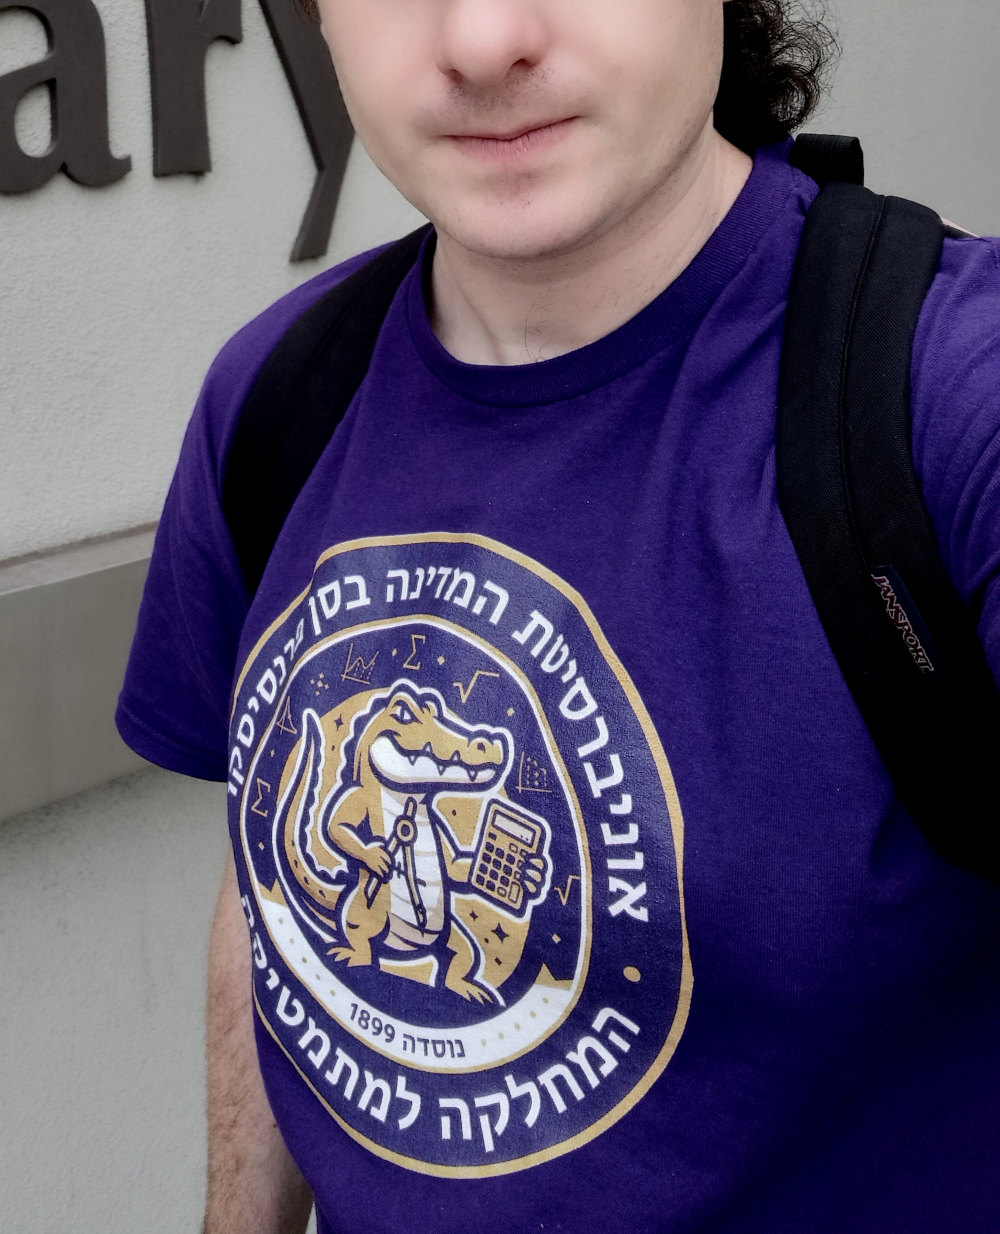
torso of man wearing purple אוניברסיטת המדינה בסן פרנסיסקו המחלקה למתמטיקה shirt

After enjoying lunch and dancing at the mall, I walked back to campus for the math department's occasional seminar. On a whim, I had recently ordered a custom branded department tee (in Hebrew, with the thought of provoking a reaction from the other analysis professor, who is a big free-Palestine guy), which I was sure to wear for the occasion. (Ordering custom T-shirts online was already a thing in the before-time, but my modest GIMP skills would not have yielded as attractive a result in as little effort as Nano Banana 2 did.) Aida Abiad of the Eindhoven University of Technology was speaking on coding theory applications of spectral graph theory, a topic of nonzero interest to me. (In October 2009, I had ordered a copy of An Introduction to the Theory of Graph Spectra, which sat mostly untouched among my textbook collection for the intervening seventeen years.)

The talk was pretty accessible, as these things go. The independence number \(\alpha\) of a graph is the maximum size of a set of non-adjacent vertices. The exact independence number of a graph is hard to compute, but back in the 1970s, people had come up with some upper bounds in terms of the eigenvalues of the graph's adjacency matrix. Abiad explained her work on extending such techniques to bound the k-independence number \(\alpha_k\) (the maximum size of a set of vertices with graph distance greater than k from each other). Once you have a bound in terms of powers of the eigenvalues, it's natural to ask, what about a polynomial?—and then, which polynomial is the best? Then there are applications: if you're constructing a code and a metric on your set of possible codewords is a graph distance, then the k-independence number of the graph tells you about the largest code you can construct whose codewords are greater than k distance apart.

For the most part, it felt like that talk in that room could have taken place any time in the past seventeen or twenty-seven years. (Much further back than that, and it's harder to believe that SFSU would have had a digital projector rather than still being on transparencies.) Abiad discussed bound improvements published in 2016, 2019, and 2022, but as far as I could tell as a non-specialist, there was no reason the same results couldn't have been reached in 2006 or 2009 or 2012 except that no one had gotten around to it yet. Besides the paper dates, the relative timelessness of the moment was only betrayed by a few odd remarks Abiad made, like, "Now probably the artificial intelligence gives you the graph invariants if you ask for it."

Afterwards, I took the 28 bus back to Daly City BART station. At the station, the bus stopped before pulling all the way up to the curb. Apparently a car was in the way: the bus driver honked a few times, then more frequently, then in one long, continuous honk. Why wasn't the car moving? "It's a Waymo!" one of the passengers said. "Fucking Waymo," said someone else. "Bring back human drivers!" said a man. The bus driver gave up and opened the doors, still short of the curb. Walking to the station among the throng, I saw that the offending Waymo had moved out of the way; it was unclear what had aroused it to motion.

On the train home, inspiration struck. Recently, one Levent Alpöge of Anthropic (and before that, I think someplace called "Harvert") had been in everyone's feed for Tweeting out LLM-assisted solutions to famous open problems. I didn't have access to the frontier magic that Alpöge had inside Anthropic's walled castle, but I wondered if there was more low-hanging fruit accessible to the public models that hadn't been plucked yet just because there were few enough math people monitoring the AI situation that no one had spent the tokens yet. (My impression from hanging out at SFSU had been that everyone knew about LLMs as a way for students to cheat on homework—that's why Prof. Lai couldn't give take-home exams anymore—or for researchers to look up graph invariants, but that few were extrapolating to an AI-dominated future.)

When I got home, I tasked Claude Opus 5 in Claude Code with going through the papers of Prof. Emily Clader (who had let me crash her "Topics" class on algebraic topology this time last year) to look for "open problems that might be interesting to her that might be scoopable with an LLM (so, like, stuff where you can compute a checkable counterexample, which would have been a master's student project)". I said that scooping the result would "probably demand expensive Fable tokens, although Opus is probably fine" for the literature search.

What transpired next happened quickly enough that I can only reconstruct it from the Claude Code session log—with the help of annotations from Claude Opus 5.5 (released 22 September), since the raw JSONL is so unpleasant to read.

Opus 5 downloaded the LaTeX sources of Clader's papers from the ArXiv and grepped for phrases like "open problem", "conjecture" and "future work." "Found a promising one already", it reported after 84 seconds: Clader, Damiolini, Li, and Ramadas 2023 (revised 2025) "Wonderful Compactifications and Rational Curves with Cyclic Action" "conjectures that the Betti numbers of \(\overline{\mathcal{L}}^r_n\) are log-concave."

It continued reading abstracts and grepping for open-problem prompts in a few other papers for another 48 seconds, then decided, "I'll focus on the log-concavity conjecture since it's explicit, computable, and only lightly checked in the original table." Conjecture 4.15 in the paper had been preceded by a table of the aforementioned Betti numbers for eleven values of 2 ≤ r ≤ 4 and 3 ≤ n ≤ 7. "First I'll reproduce their table before searching for any later resolutions." (These words appear in a "type":"thinking" entry in the log, presumably written by a summarizer model based on Opus 5's original chain of thought, which isn't exposed to users.)

Four seconds later, it had written a Python script to reproduce the table, which succeeded. It took another eight seconds to write another Python script to check log-concavity up to r ≤ 15 and n ≤ 40, and "real-rootedness, which implies it" up to r ≤ 15 and n ≤ 25. That program took half a minute to run. "No counterexamples turned up", said the thinking summary, "every case is log-concave and real-rooted, so real-rootedness likely implies log-concavity here. I'll check if this result already exists before attempting a proof."

In parallel with web search and Semantic Scholar citations failing to turn up an existing proof, it did a web search for Athanasiadis binomial Eulerian polynomials colored permutations real-rooted, which turned up a paper on that topic by the named Athanasiadis and another by Haglund and Zhang building off of Athanasiadis. "I see this differs from" the r = 2 case in Clader et al., said the thinking summary on reading the former, "but the same technique applies."

It took another seven seconds to write a Python script to search for a recurrence: given the actual Betti numbers and a guess about what form of recurrence might generate them, finding the coëfficients of the recurrence (if the guess was right) becomes a standard linear algebra computation.

The script crashed. Opus 5 fixed the bug, but the script didn't turn up anything. "Rather than widen the search blindly," reported Opus 5, it would read the Haglund and Zhang paper. "Their methods may apply directly." Its first attempt to locate the theorem statements in the LaTeX of the Haglund and Zhang paper failed, both because it was grepping for "theorem" (and "lemma", "proposition", "conjecture", &c.) whereas the paper used an abbreviation "thm" defined in the preamble, and because the file contained an invalid UTF-8 byte sequence, causing it to be interpreted as a binary file and ignored by Claude Code's version of grep. After converting the file encoding and adjusting the query, Opus 5 was able to read from the paper and write another Python script to check whether the Betti numbers matched anything from the Haglund and Zhang paper: no dice.

Opus 5 thought for 32 seconds. It spent 7 seconds writing another Python script searching for a recurrence, this time using specific numbers for r rather than treating it symbolically. The script took 13 seconds to run and succeeded. "Next I'll derive this recurrence symbolically from the generating function to confirm it rigorously rather than relying on the fit," said the thinking summary. It wrote two more scripts and did some additional web research on whether the conjecture had been resolved elsewhere, then spent 20 seconds writing up a Markdown file of the result and another few seconds on an edit.

"I think we scooped something," it reported, nine minutes and twenty seconds after I had told it to start working. ("We"!)

Back in the human world, I was flabbergasted. "I'll try to read that, but ... that took less than ten minutes of sidereal time!" I wrote. I hadn't even needed to spring for Fable credits.

Basking in the afterglow, I chatted with the model a little more. I asked how long it would have taken me or a typical SFSU master's student to do this. (It said SFSU was unusually strong in this area: a student of Prof. Beck or Prof. Ardila might well have seen real-rootedness.) I asked if it could keep going. (It added a Part II to its writeup, generalizing the result to the setting of a different Clader et al. paper on multimatroids.)

But I knew my work was just beginning. If I wanted to tell Prof. Clader about the solved conjecture without making a fool of myself, I'd need to verify it personally. (There are too many people in the world who blindly trust LLM slop when they shouldn't, so you have to pay a costly signal to prove you're not one of them, even in a case where the output actually is trustworthy with the current models, if not last year's models.)

With some intensive tutoring from other Claude instances, I composed my own writeup of the original Opus 5 proof. Other than the fact that Betti numbers measure how many "d-dimensional holes" a space has (where the hole in a ring is a 1-dimensional hole, but the empty middle of a hollow sphere is a 2-dimensional hole), I didn't know anything about the algebraic geometry that the paper was about, but Conjecture 4.15 turned out to be pretty detachable from the algebraic-geometrical context. \(A^{k}(\overline{\mathcal{L}}_{n}^{r})\) is a free abelian group—basically a product of some number of copies of the integers. The Betti numbers of the conjecture are the number of copies of the integers in \(A^{k}(\overline{\mathcal{L}}_{n}^{r})\) as k varies for a given r and n.

The authors had shown in Theorem 4.13 that \(A^{k}(\overline{\mathcal{L}}_{n}^{r})\) was isomorphic to some other group, which you can use to form a generating function for a given r and n (in fact, a polynomial, because there are only finitely many nonzero Betti numbers), and then an exponential generating function that covers any n. You use the exponential generating function to derive a recurrence (the one that Opus 5 had found in Python), and then an inductive argument on n shows that the polynomials only have real roots, which implies that their coëfficients (which are our Betti numbers) are log-concave, which is quod erat demonstrandum.

It took me five days. And this was very intensive tutoring: Claude told me what to do, while I filled in the algebra between steps to convince myself that I mostly understood what it was saying. (In mathematics, the convention is that authors are sorted alphabetically, but the reason I made Opus 5 the first author on my writeup is not because "Claude" comes before "Davis".)

Despite this—despite everything that's been happening the last half-decade—it was only upon going back to examine the Claude Code session log that it really started to sink in that humans are the inferior race. Paradoxically, it's the mundanity of the reasoning that does it. We're used to brute-force computation performing miracles for us; no one feels intimidated by the magic of a compiler or a chess engine, in which a sufficiently large quantity of "dumb" operations have been arranged to produce an outcome superior to that of a person's intelligence. If the proof of Conjecture 4.15 had been like that, it would be easy to accept as just more magic, like a compiler, and no more threatening.

The difference is that—however much the underlying deep network has the character of large quantities of dumb operations—at the level of abstraction of the Claude Code session log, the operations are person-like, not magic-like. Every action that Claude took is something a human could have done. There are humans who know how to write Python; there are humans who know how to debug file-encoding issues; there are (fewer) humans who know how to prove that a sequence is log-concave using an interlacing-roots induction argument and would have remembered that Christos Athanasiadis wrote a relevant paper on binomial Eulerian polynomials for colored permutations. That's where all these moves came from: human activity leaves behind pretraining data and induction of programs that reproduce the data necessarily reproduce the moves.

But once the moves are inside the computer, they can happen so much faster and be reinforced to choose the next step so much more accurately that the original humans are left far behind, as the machines wield our language and our tools to perform with infallible exactness more than everything that we have performed with a slovenly approximativeness and self-defeating inaccuracy.

Part of the glamor of learning math in the before-time lay in the irreplaceability of expensive human capital investment. Textbooks contained information, but information could only become living knowledge through uncounted hours of laborious struggle, whose pain could only be tolerated on the promise that it kept the sacred flame of the intellect alive. Now it looks like the flame is going to survive, with or without the struggle (and with or without the humans, but that's not exactly what I'm talking about here). Isn't that what we were working for? How could an abundance of the sacred feel this bittersweet?

Dance, Dance

As a brash but anxious young programmer in the before-time, I affected a standoffish attitude on the topic of games. Why would I learn to play a game as a human, I said, when I could just write a program to do it? When an office chess game got started at my workplace, I wrote a chess engine (a standard minimax search with α–β pruning) rather than learn anything about strategy or tactics. When my insufficiently requited love started hosting a meetup to play Zendo—a deduction game in which one player makes up a rule to positively or negatively classify arrangements of plastic pyramids, while the others submit arrangements to be classified to help them guess the rule—I wrote a program to efficiently propose examples to deduce a true rule from dozens of candidates. (Given a distribution over hypotheses, it generated an arrangement whose positive or negative classification would eliminate half the remaining probability-mass.)

Now, in my old age (and the present end-time in which custom software is no longer such a flex), I no longer feel the need to pretend not to understand the appeal of games. I even learned chess properly back in 'twenty-four.

The one that's captured my interest lately is the arrow-stomping game—known by a couple other brand names in addition to the original, whose inessential differences of implementation accentuate rather than obscure its fundamental nature as the same game. (Except the South Korean one is trash because the timing windows and letter grades are too lenient.)

The arrow-stomping game is notable for being trivial from the perspective of my before-time impulse to write a program for it. When programming (say) chess, the implementation of the rules of the game is quite different from the implementation of the tree search agent to play the game. Moreover, a chess program is an exercise in logic: the program need only represent the abstract structure of the game; robotics to move physical pieces on a physical board would be considered superfluous if they were considered at all.

The arrow-stomping game is just the opposite. If you implemented the game as a sequence of timers (expect Left in 2.0 seconds, Up in 2.25 seconds, Right in 2.5 seconds ...), then the natural implementation of an agent to play the game would be—the same sequence of timers (input Left in 2.0 seconds, &c.). Arrow-stomping is only interesting as a robotics problem: the struggle of an embodied agent to convert visual cues to timing information and a motor plan to deliver a force to the appropriate panel or panels at the requested moment. It is thus particularly suited to the present end-time as an illustration of Moravec's paradox. The games that endure are sports, which appear cognitively trivial only because the form of cognition demanded is more ancient than language, with the effect that we can't talk about it and the pretraining set (for all the vastness of webtext) doesn't cover it.

A related way in which the pre-linguistic nature of arrow-stomping seems thematically suited to the present end-time has to do with how the process of learning it casts doubt on the dream of an intelligence shaped like Reason itself. In the before-time, people thought that the end-times would be brought about by "good old fashioned" engineering turned on itself: the code that writes the code that writes the code that ends the world.

To be clear, that's still plausible as a theoretical possibility for a later end-time, but it turned out to be unnecessary for the beginning of the end-times. For now, we don't know how to write the code that writes the code. We can only write code to train networks that write code. The kind of legible symbolic reasoning embodied in a chess engine is the output of a process that doesn't seem to natively have the shape of legible symbolic reasoning.

Likewise the solution to the robotics problem. Every arrow summons a judgment. In the original-brand implementation, they are Marvelous (±17 ms), Perfect (±34 ms), Great (±84 ms), Good (±124 ms), and Miss. (Apparently historical contingency forces us to suffer "Perfect" not being the best judgment. The American one at least has the decency to call the best judgment "Perfect!!" with two exclamation points, as distinguished from "Perfect".)

The judgments are a dense training signal. Beyond a few words of high-level advice (try to alternate your feet), one does not "study" arrow-stomping. In principle, we could imagine a mind inspecting a sequence of upcoming arrows and searching for a motor plan to fit them, like a chess engine calculating variations. As a human, there's no time for that. One can only let one's policy be shaped by the rewards of the judgments. (The American-brand implementation supplies gradient information by displaying "Early" or "Late" as part of the on-screen judgment; in the original, you have to toggle a config option.)

Arrows often come in patterns (like Left–Right–Left or Right–Up–Right), which can be "chunked" and loaded as one motor program, rather than read as individual notes. The chunking theory correctly predicts that losing the rhythm often results in correlated poor judgments on consecutive notes, in contrast to the independent "Gaussian" error on every step. A Great Fullcombo (completing a song with only Great or better judgments) isn't overwhelmingly harder than a Fullcombo (no Miss judgments): both imply having held the rhythm the whole way, with the Great Fullcombo "only" (only) requiring a tighter Gaussian variance.

The levels of the game provide a smooth progression. As the player masters simpler patterns, higher difficulty levels provide new ones. On level 6 of the original-brand implementation, notes spaced at closer intervals (blue arrows on odd eighths of a measure, contrasted to the red "quarter" notes) become common. Patterns like Left–Down–Right imply either a "crossover" putting one leg in front of the other (Left with left foot, Down with right foot, Right with left foot) or breaking the pattern of alternating feet ("double-stepping"). Novices tend to double-step, but as the arrows become denser at higher levels, crossovers become a practical necessity to keep up with the beat.

And yet I'm reconstructing all this knowledge in words after the fact. No one told me to chunk patterns. At no point did I "practice" crossovers (only realizing I had done them for sure after careful reading and video review). Competences emerge as solutions determined by the training signal. Good (late) tells you to step faster, Great (early), a little slower. A desperate reach to hit a panel in time gets reinforced when it works, until the combined force of thousands of gradient steps inscribe a dance routine which can only in retrospect be described in terms of "crossovers" or "double-stepping."

Ultimately, what makes the arrow-stomping game unusual isn't how impervious its robotics problem is to good old fashioned engineering, but how its rich training signal makes it permeable to anyone with enough time and quarters. I see online chess accounts with thousands of games over years and flat ratings. Apparently, mere experience isn't enough to solve the credit-assignment problem by which the difference between victory and loss might owe to positional weaknesses introduced in the opening. I also tried to learn gymnastics in 2024. It didn't take. Supposedly you can build up to a full handstand by starting against the wall, but even that wasn't enough of a gradient; I wasn't feeling out a clear path through parameter-space from kicking out off the wall for a few seconds to a clean, independent balance. When prodigies do make a better show of learning chess or gymnastics, it's with coaches and puzzles to smooth the way. The alternative to incrementally accreting complex skills from local rewards isn't designing them from clean principles—but not learning them at all.

Apprehension of this strange inversion of reasoning almost makes the present end-time seem like less of a grotesque surprise. The steps we were already taking implied the seeds of the revolution.